You click Pay in an online shop, and half a second later the page says "Order placed". Behind that click, the code in your browser called the shop's frontend, the frontend called the orders backend, and the backend asked a handful of other programs for help: who is this (auth), what's in the cart (cart), is it in stock (inventory), take the money (payments), and write the order down (the orders database). Each of these is a service, a program that answers requests from other programs over the network, and a service that another service calls on is its dependency. The click works only if all five dependencies answer.
Suppose each of the five is excellent and answers correctly 999 times out of 1,000. It's natural to expect the click to be about that reliable. It won't be. It will fail more often than any single dependency, and when conditions get bad, the services' own attempts to recover (asking again, queueing more work) can turn a small hiccup into an outage that lasts hours after the original problem is gone.
This chapter follows that one click and asks: how often will it work, how do we decide how often it should, and what stops one sick service from taking the whole shop with it? We'll start with the arithmetic, turn it into a target we can measure and spend, and then add the defences one at a time, each one because the one before it leaves a gap: timeouts, retries, circuit breakers and load shedding.
01How often the click works
1.1Counting in nines
We need a way to say how often something works. The usual one is availability, the share of time it works, written as a percentage. A service that works 999 minutes out of every 1,000 is 99.9% available. People call that "three nines", and 99% is "two nines", 99.99% is "four nines".
Each extra nine divides the allowed failure by ten, which makes the allowed downtime shrink fast. Over a 365-day year, 99.9% allows about 526 minutes of downtime, which is under nine hours, while 99.99% allows about 53 minutes. (Later in the chapter we'll count requests instead of minutes, which is how reliability is measured in practice, but the arithmetic is the same.)
1.2Why five good services make a worse one
Now back to the click. It needs auth, cart, inventory, payments and the orders database, and if any one of them fails to answer, the click fails. Suppose each answers 999 times in 1,000, and that their failures are unrelated to each other. The click works only when all five work, so the chance of that is 0.999 × 0.999 × 0.999 × 0.999 × 0.999, which is 0.999 to the fifth power.
Think of a relay team where every handoff can drop the baton. Each extra handoff multiplies the chance of a clean race by a number just under one, so a long chain of very good handoffs still loses more often than any one of them. Dependencies work the same way. You can put numbers on it with a dozen lines of Python. Save this as nines.py and run it with python3 nines.py. The first loop prints, for four availability levels, how many minutes of downtime that level allows per year and per 30 days. The second loop raises 0.999 to the power of 1, 3, 5 and 10 and converts what's lost into hours per year. (The :>13.3% pieces are format codes that right-align a number and print it as a percentage.)
year_min = 365 * 24 * 60
print(f"{'availability':>13} {'downtime / year':>17} {'downtime / 30 days':>19}")
for a in (0.99, 0.999, 0.9999, 0.99999):
    print(f"{a:>13.3%} {(1 - a) * year_min:>13.1f} min {(1 - a) * 30 * 24 * 60:>15.1f} min")

print()
for n in (1, 3, 5, 10):
print(f"{n:>2} dependencies, each 99.9%, all needed: {0.999 ** n:.3%} ({(1 - 0.999 ** n) * year_min / 60:.1f} hours down a year)") availability downtime / year downtime / 30 days
99.000% 5256.0 min 432.0 min
99.900% 525.6 min 43.2 min
99.990% 52.6 min 4.3 min
99.999% 5.3 min 0.4 min
1 dependencies, each 99.9%, all needed: 99.900% (8.8 hours down a year)
3 dependencies, each 99.9%, all needed: 99.700% (26.3 hours down a year)
5 dependencies, each 99.9%, all needed: 99.501% (43.7 hours down a year)
10 dependencies, each 99.9%, all needed: 99.004% (87.2 hours down a year)In the top table you can see the factor of ten: 99.9% allows 525.6 minutes a year and 99.99% allows 52.6. The bottom lines are the click. One dependency at 99.9% costs 8.8 hours of downtime a year, and our five-service click costs 43.7 hours, about five times as much, because each dependency's failures add to the total. Ten dependencies cost about 87 hours, and the click is down to roughly 99.0%, two nines.
1.3What you can do about it
Here are the numbers so far side by side, with one extra row at the bottom that we'll come to in a moment.
| One dependency at 99.9% | 0.999 | 99.9% |
| Five in series | 0.999⁵ | 99.50% |
| Ten in series | 0.999¹⁰ | 99.00% |
| Two replicas at 99%, either will do | 1 − 0.01² | 99.99% |
| ten 99.9% dependencies leave you at | two nines | |
If the shop wants to promise 99.9% and needs five dependencies that each deliver 99.9%, it has already broken the promise on paper, before any bug of its own. There are three moves: make the dependencies better, need fewer of them at once, or let the click survive when one of them fails.
Of the three, the last is probably the most useful, and the bottom row of the table shows one way to do it. Run a replica, a second copy of a service, so the click needs either copy and not a particular one. Each copy at 99% fails 1 time in 100, so both fail together only 1 time in 10,000 (0.01 × 0.01), and the pair is 99.99% available. When the click needs every dependency, each one's chance of failing adds to the total. When it needs only one of two copies, the chances of failing multiply together and become tiny.
That works only if the failures are independent. Two replicas that both read the same bad configuration push, or that sit in the same data centre during a power event, fail together, and the pair is no better than one copy.
So the arithmetic tells us what the shop can achieve. It doesn't tell us what the shop should promise, or how anyone would know whether the promise was kept. For that we need a target made of numbers that someone can measure.
02Putting a number on reliability
"The shop should be reliable" can't be tested, alerted on or traded off against anything. The first job is to turn it into a number.
2.1SLI, SLO and SLA
Start by deciding what counts as a click working. Say a request is good if the shop answers it without a server error (an HTTP status in the 500s, written 5xx) in under 300 milliseconds. Count the good requests and the valid ones, which are the requests that count towards the measurement. The ratio of good to valid is called the SLI, the service level indicator: it's the measurement itself, such as "the share of requests answered well".
Next comes a target for that measurement over a window of time. Say 99.9% of requests good, over a rolling 30 days (a window that always covers the most recent 30 days). That target is the SLO, the service level objective. If the target is written into a contract that has consequences when it's missed, that contract is the SLA, the service level agreement.
| Term | What it is | Example |
|---|---|---|
| SLI (indicator) | A measurement of good events over valid events | Share of HTTP requests that returned non-5xx in under 300 ms |
| SLO (objective) | A target for the SLI over a window | 99.9% of requests good, over a rolling 30 days |
| SLA (agreement) | A contract with consequences if the SLO is missed | Service credits below 99.5% in a calendar month |
Set the SLA looser than the SLO, and the SLO looser than what the service usually achieves. The gap between them is warning time: the team should learn that it's missing the internal target long before a contract notices.
?Why measure requests instead of uptime?
Because "the server was up" isn't what users experience. A service can answer health checks all day while 5% of real requests time out. An SLI counted from real requests, ideally at the load balancer (the program in front of the servers that spreads requests across them) or in the client, sees what users see.
An SLI should also be a ratio of events and not an average or a percentile. "p99 latency under 300 ms" (the time that 99 of every 100 requests beat) is hard to budget against. "99% of requests completed in under 300 ms" is a count of good events that you can add up across servers and over time.
2.2What each nine costs
To pick the number, we need to know what each level asks of the team. Here are the allowed bad minutes at each level:
| SLO | Bad time per year | Per 30 days | Per week |
|---|---|---|---|
| 99% | 3.65 days | 7.2 hours | 1.68 hours |
| 99.9% | 8.77 hours | 43.2 minutes | 10.1 minutes |
| 99.95% | 4.38 hours | 21.6 minutes | 5.04 minutes |
| 99.99% | 52.6 minutes | 4.32 minutes | 1.01 minutes |
| 99.999% | 5.26 minutes | 25.9 seconds | 6.05 seconds |
?Why don't teams just aim for five nines?
Because of what the last row implies about people. Twenty-six seconds a month is less time than it takes a person to notice an alert, unlock a laptop and log in. At four or five nines, detection and recovery have to be automatic, rollouts have to be gradual enough that a bad one hurts a sliver of traffic, and every dependency has to be better still. Each extra nine is a different engineering organisation and costs far more than a tweak to the last one.
2.3Checking the promise against the dependencies
Section 1 gave us the check: the shop's SLO can't be higher than what its critical dependencies allow. Google's rule of thumb, from The Calculus of Service Availability (Treynor et al., 2017), is the rule of the extra 9: a critical dependency should offer one more nine than the service that depends on it. When a dependency can't, we change it from critical to something the click can survive without, using a cache, a fallback or graceful degradation (section 6.3 lists the options).
A 99.9% SLO says something else that turns out to be more useful than "be reliable": 0.1% of requests are allowed to fail. The next section is about what to do with that allowance.
03Error budgets and burn rates
3.1A budget meant to be spent
The allowance of failures that the SLO permits is the error budget. Say the shop's API takes 1,000 requests a second. Over 30 days that's about 2.6 billion requests, and a 99.9% SLO allows about 2.6 million of them to be bad. That's the budget, and it's meant to be spent: on deploys, experiments, migrations and the occasional bad day.
?Why is a budget better than "as reliable as possible"?
Because it turns an argument into a measurement. When the budget is healthy, the team ships faster. When it's nearly gone, the team slows releases and spends time on reliability. Nobody has to win a debate about whether the service is "reliable enough"; the counter says.
A budget also caps how reliable the service should be. A service at 99.99% against a 99.9% SLO is leaving budget unspent, which usually means it's shipping more slowly than it could.
3.2Burn rate
A budget raises a new question: how fast is it being used up? The burn rate compares the current speed of spending to the speed that would use the budget up exactly at the end of the window. A burn rate of 1 spends a 30-day budget in 30 days. A burn rate of 10 spends it in 3.
For a 99.9% SLO the budget is 0.1% of requests, so the burn rate is just the current error rate divided by 0.1%:
| Error rate | Burn rate | Budget gone in |
|---|---|---|
| 0.1% | 1 | 30 days |
| 0.6% | 6 | 5 days |
| 1.44% | 14.4 | 50 hours |
| 10% | 100 | 7.2 hours |
| 100% (full outage) | 1,000 | 43 minutes |
Your service has a 99.9% monthly SLO. A bad deploy starts failing 1.44% of requests. What share of the month's error budget is gone after one hour?
3.3Alerts on burn rate
Now we can decide when to wake someone. An alert that wakes the on-call engineer is called a page. The obvious first rule is a fixed threshold on the error rate, something like "5xx above 1% for five minutes". It goes wrong in both directions. A blip that crosses 1% for five minutes burns at a rate of 10 for five minutes, which is only about 0.1% of the month's budget, yet it pages someone at 3 a.m. Meanwhile a slow leak at 0.5% errors never crosses 1%, so it never pages, and in three days it spends half the budget (burn rate 5 for 72 hours). The alert should follow how fast the budget is going, and not how the graph looks.
So we choose how much budget loss should wake someone. The SRE workbook's chapter on alerting on SLOs walks through several schemes and ends on this one, where each alert fires only if the burn rate is high over both a long window and a short one:
| Severity | Long window | Short window | Burn rate | Budget consumed when it fires |
|---|---|---|---|---|
| Page | 1 hour | 5 minutes | 14.4 | 2% |
| Page | 6 hours | 30 minutes | 6 | 5% |
| Ticket | 3 days | 6 hours | 1 | 10% |
A ticket is a task for working hours and wakes nobody. Each budget figure comes from one formula, burn rate × window ÷ SLO period. For the first row, 14.4 × 1 h ÷ 720 h = 2%.
?Why two windows per alert?
A long window stops the alert firing on a blip: 14.4× burn over a whole hour is real. The short window, a twelfth of the long one by the workbook's guideline, makes the alert stop firing soon after the problem is fixed, instead of paging for the rest of the hour while old errors age out of the long window.
Here's how the three alerts behave during one incident:
In Prometheus, a monitoring system that stores counters over time, the fast-burn page is two ratio queries joined with and. In each one, rate(...[1h]) is the per-second average over the last hour, sum adds up all the servers, and dividing the 5xx count by the total gives the error ratio. The threshold is the burn rate times the 0.1% budget, 14.4 × 0.001:
(
  sum(rate(http_requests_total{job="api",code=~"5.."}[1h]))
  / sum(rate(http_requests_total{job="api"}[1h])) > (14.4 * 0.001)
)
and
(
  sum(rate(http_requests_total{job="api",code=~"5.."}[5m]))
  / sum(rate(http_requests_total{job="api"}[5m])) > (14.4 * 0.001)
)
The alerts now tell us when the budget is draining. Next we need to know what drains it. Besides services that go down, the most common cause is a service that gets slow, and a slow dependency is worse for its callers than a dead one.
04Timeouts and deadlines
4.1A call with no timeout
A dead service refuses the call at once, and the caller can fail quickly. A slow service takes the call and doesn't answer, so the caller waits. To see what that does, we need to know how a backend handles clicks. Each request being handled occupies a thread, a worker inside the backend program, and a backend has a fixed number of them, its thread pool. When the orders database gets sick and takes ten seconds to answer, every thread that calls it is stuck for ten seconds. Here's that on a pool shrunk to four threads so we can draw it:
A call with no timeout turns a dependency's latency into the caller's resource usage. We can count how much. The number of requests in flight at once equals the arrival rate times the time each takes, a relationship known as Little's Law (chapter 16 covers it). At 500 requests a second, a database that goes from 20 ms to 10 seconds takes the in-flight count from 10 to 5,000. If the pool has 200 threads, the backend is down.
A common extra guard borrows its name from ships, whose hulls are divided into watertight compartments so one leak floods only one compartment. Give each dependency its own separate thread pool, and a sick database can fill only the database pool while calls to cart or auth still find free threads. That separate pool is called a bulkhead, and a bulkhead would also have kept the health check in the scene above from waiting.
?Why not just set every timeout to something generous, like 30 seconds?
Because a generous timeout is almost no timeout. It lets a stuck dependency hold resources for 30 seconds each, which is exactly the pile-up above. A timeout should be close to the latency a healthy dependency has.
A workable rule, roughly: start from the dependency's p99.9 under normal load (the time that 999 of every 1,000 calls beat), add a margin, and check what share of calls would have timed out last week. If a healthy dependency trips the timeout often, it's too tight. If a stuck one can hold a thread for many times its normal latency, it's too loose.
4.2Deadlines across several hops
Our click isn't one call. The frontend calls the backend, which calls the database, and if each hop picks its own timeout, the timeouts don't add up to anything sensible. The frontend gives up after 1 second, but the backend it called is still waiting 2 seconds on the database, doing work nobody will read.
One fix is a deadline: an absolute time by which the whole request must be done, passed down with each call, so that every hop knows how much time is left. The SRE book's chapter on cascading failures gives the arithmetic for a remote procedure call (RPC), a call from one service to another: if server A picks a 30-second deadline and spends 7 seconds before calling B, "the RPC from A to B will have a 23-second deadline."
gRPC, a popular RPC framework, does this for you: a client's deadline travels with the request in a grpc-timeout header, and a server that hands the incoming request's deadline to its own outgoing calls passes on whatever time is left. Over plain HTTP you have to carry the deadline yourself, in a header, and check it before starting expensive work.
A timeout turns a stuck call into a failed one. But many failures last only a moment: a dropped packet, a server restarting, a database replica taking over from a copy that failed. The cheapest answer to a momentary failure is to ask again.
05Retries, backoff and jitter
A retry hides a transient failure at the cost of one more request, which makes it the cheapest reliability feature there is. It's also the most common way a small problem becomes a big one, and the rest of this section is about how.
5.1What's safe to retry
Before how to retry comes whether. Think about the Pay click. The backend asks payments to charge the card, payments charges it, and the response is lost on the way back. The backend sees a timeout and retries, and the customer is charged twice. A retry is only safe if doing the operation twice leaves things the same as doing it once, a property called idempotent.
| Operation | Safe to retry? | Why |
|---|---|---|
GET, reads | Yes | No side effects |
PUT of a full value, DELETE | Yes, by design | Idempotent: the second call leaves the same state |
POST that creates or charges | Only with an idempotency key | The first call may have succeeded before the response was lost |
| Call that timed out | Only if idempotent | A timeout means "unknown", not "failed" |
For the third row, the standard fix is an idempotency key: the client generates a unique ID per logical operation and sends it on every attempt. Stripe's design (Brandur Leach, 2017) has clients send it in an Idempotency-Key header, and when a retry arrives for a key that already succeeded, "the server replies with a cached result of the successful operation". The retried charge then returns the first charge's receipt, and the customer pays once.
5.2Retries multiply
Safe retries still have a problem in a layered system: each layer that retries multiplies the load on everything below it. Our click passes through three callers, the browser's code, the frontend and the backend, before it reaches the database. To draw it, let every layer try at most twice, one try and one retry, and watch what reaches the database when it's overloaded and failing:
These numbers come from the SRE book's own example: with backend, frontend and JavaScript layers each issuing 3 retries, "a single user action may create 64 attempts (4^3) on the database." Its advice is to "avoid amplifying retries by issuing retries at multiple levels."
?Why not just retry at the top?
Retrying at the top is safest for load, but it's a bit slow: the whole call tree is redone for a failure in one leaf. The usual compromise is to retry at exactly one layer, the one closest to the failure that knows the operation is idempotent, and to have every other layer pass errors straight up.
5.3Backoff, and why it needs jitter
Even with one retrying layer, a client that retries immediately adds load at the worst moment. So retries wait, and wait longer after each failure. This is called backoff. Marc Brooker's Exponential Backoff And Jitter (AWS Architecture Blog, 2015) is the standard reference, and it defines the variants below. In the formulas, base is the first wait, cap is the longest wait allowed, and n is the number of the attempt. Some schemes make the wait partly random, and that randomness is called jitter:
| Scheme | Sleep before attempt n | Behaviour |
|---|---|---|
| Exponential | min(cap, base × 2^n) | Spreads retries out in time, but every client waits the same amount |
| Full jitter | random(0, min(cap, base × 2^n)) | Same ceiling, uniformly spread below it |
| Equal jitter | half the exponential value, plus random over the other half | Never retries very early |
| Decorrelated jitter | min(cap, random(base, previous × 3)) | Each client's delay depends on its own last delay |
?Why isn't plain exponential backoff enough?
Because clients that failed together retry together. If a thousand clients hit an error at the same instant, exponential backoff moves the whole thousand to 1 second later, then 2, then 4. The spike is postponed, and each wave meets the same capacity limit as the first.
A simulation makes that concrete. A thousand clients send at once to a server that accepts 10 requests per millisecond and rejects the rest. Rejected clients back off with base 1 ms and cap 1 second, and retry until they succeed. Besides the four schemes in the table, it runs "none" (retry after 1 ms, with no backoff) and "grpc" (exponential, with each wait multiplied by a random number between 0.8 and 1.2, the small jitter gRPC uses). The code block shows how each policy picks its sleep, and the table shows how many calls the thousand clients made in total and when the last one finished:
for c, attempt, last in arrivals_this_ms:     # shuffled
    if accepted < CAP: accepted += 1; continue # CAP = 10 per ms
    exp = min(cap, base * 2 ** attempt)        # base 1 ms, cap 1000 ms
    sleep = {
        "none":   base,
        "exp":    exp,
        "grpc":   exp * uniform(0.8, 1.2),
        "equal":  exp / 2 + uniform(0, exp / 2),
        "full":   uniform(0, exp),
        "decorr": min(cap, uniform(base, last * 3)),
    }[policy]
schedule(c, attempt + 1, at=now + max(1, round(sleep)))policy total calls all done after
none 50,500 99 ms
exp 50,500 90,023 ms
grpc 7,410 531 ms
equal 7,029 230 ms
full 7,226 311 ms
decorr 7,341 189 msIdeally, 1,000 calls finish at 100 ms, because that's how fast the server can accept a thousand requests. Retrying every millisecond with no backoff finishes on time but sends 50 times the necessary calls. Unjittered exponential backoff is the worst of both: the same 50,500 calls, and the last client waits 90 seconds, because all thousand stay synchronised and keep colliding. Every jittered variant cuts the work to about 7,000 calls and finishes in under a second.
Brooker's own simulation, of clients competing to update the same record, reaches the same verdict: jittered backoff "should be considered a standard approach for remote clients," with full jitter using the least work and decorrelated jitter finishing slightly sooner.
5.4Retry budgets
Backoff controls when each client retries. It doesn't limit how much retrying a fleet of clients does in total, and under a real overload that total is what matters. A retry budget caps retries as a share of normal traffic. Three real designs are in the table below. One of them belongs to Envoy, a proxy: a program that sits between callers and a service and forwards their requests, so it can count and limit them on the way through. We'll meet Envoy again in section 6.
| System | Rule | Default |
|---|---|---|
| Google (SRE book, Handling Overload) | Up to 3 attempts per request, and retry only while retries are under 10% of a client's requests | 10% per client |
Envoy retry_budget | Retries in flight ≤ a percentage of the requests in flight plus those waiting | 20%, minimum 3 concurrent |
| gRPC retry throttling | A counter of tokens: failures cost 1, successes earn tokenRatio; no retries at or below half full | Set per service config |
gRPC's version is small enough to read whole. Its counter is a token bucket: a supply of tokens that failures spend and successes refill. Each failed attempt calls throttle(), which removes one token and answers "throttle this retry?" with yes whenever the tokens are at or below the threshold, half the maximum. Each success calls successfulRPC(), which adds ratio tokens back, up to the maximum.
type retryThrottler struct {
	max    float64
	thresh float64   // set to max / 2 from the service config
	ratio  float64

	mu     sync.Mutex
	tokens float64
}

// throttle subtracts a retry token from the pool and returns whether a retry
// should be throttled (disallowed) based upon the retry throttling policy in
// the service config.
func (rt *retryThrottler) throttle() bool {
	/* ... nil check ... */
	rt.mu.Lock()
	defer rt.mu.Unlock()
	rt.tokens--
	if rt.tokens < 0 {
		rt.tokens = 0
	}
	return rt.tokens <= rt.thresh
}

func (rt *retryThrottler) successfulRPC() {
	/* ... nil check ... */
	rt.mu.Lock()
	defer rt.mu.Unlock()
	rt.tokens += rt.ratio
	if rt.tokens > rt.max {
		rt.tokens = rt.max
	}
}?Why does a budget beat a per-request retry limit?
Because a per-request limit of 3 still allows 4× load when everything is failing, which is exactly when the backend can least afford it. A budget scales retries with success: when most calls succeed, the odd failure gets retried. When most fail, the tokens drain and retries stop, and the backend sees roughly its normal load.
A budget stops us from making a failing dependency worse. It doesn't spare us the cost of calling one that is clearly down. While payments is dead, every click still sends its first call there and waits out a timeout, and the backend's threads keep filling up. We need something that notices the dependency is down and stops calling it.
06Circuit breakers
6.1Three states
A circuit breaker works like the one in a house: when a dependency is clearly failing, it trips, stops calling it for a while and fails fast instead. The pattern comes from Michael Nygard's Release It! and Martin Fowler's CircuitBreaker write-up. A breaker is always in one of three states. In the closed state, the circuit is complete and calls flow through as normal. In the open state it has tripped and calls fail at once. In the half-open state it lets a few trial calls through to find out whether the dependency has recovered.
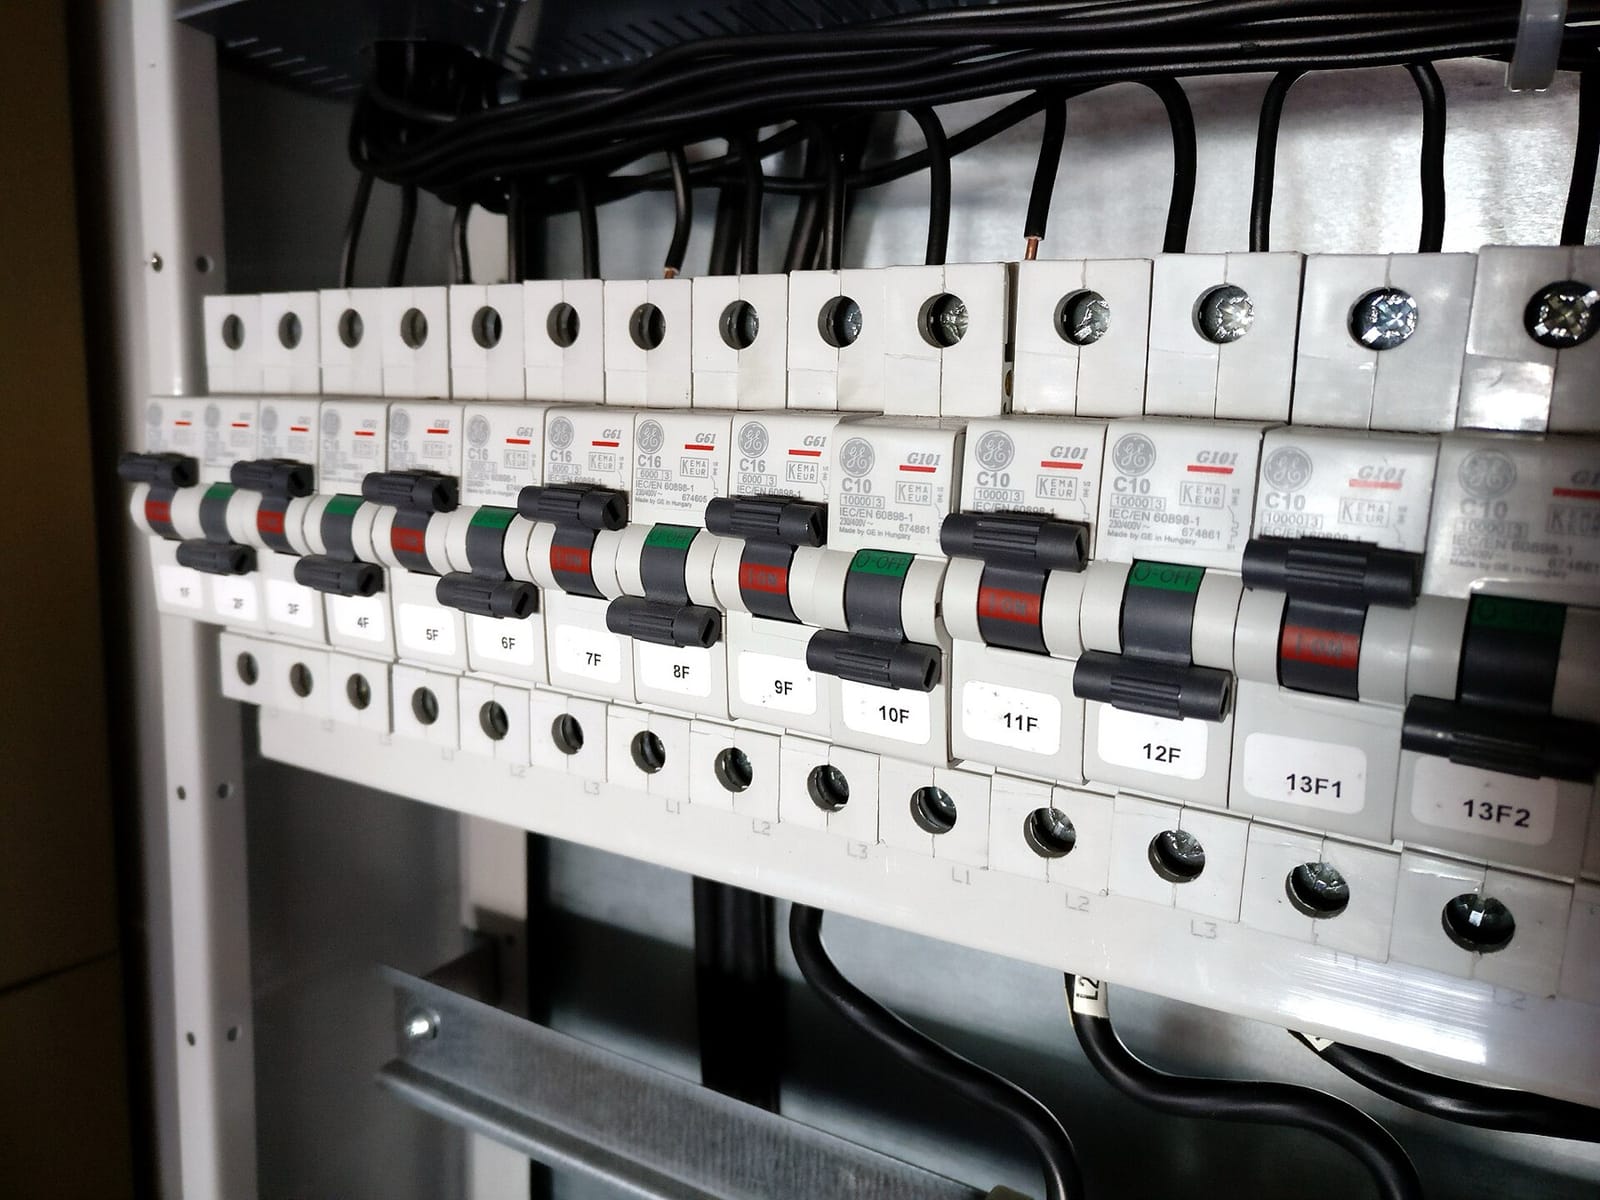
Resilience4j, a common circuit-breaker library for programs on the Java platform, has these three states plus some special ones, and its documented defaults make the state machine concrete. Here's a breaker on default settings sitting between the backend and the payments service:
minimumNumberOfCalls).?Why fail fast instead of waiting for the timeout?
Two reasons. For the backend, a failed call that returns in microseconds frees the thread, where a call that waits out a 2-second timeout holds it. For the dependency, zero traffic is often what it needs to recover: an overloaded database with its queue drained can come back, and one still receiving retries can't.
6.2Envoy's circuit breakers are concurrency limits
Envoy uses the same name for something different. Envoy calls the service it forwards requests to the upstream, and the group of servers that together provide one upstream service a cluster. Its "circuit breakers" are limits on how many connections and requests can be in flight to one cluster at once. They have no states to move through: each request that would push a count over its limit fails, and the next request that fits goes through. Here are the limits and their defaults, starting with the retry budget from section 5.4:
    message RetryBudget {
      // Specifies the limit on concurrent retries as a percentage of the sum of active requests and
      // active pending requests. [...]
      // This parameter is optional. Defaults to 20%.
      type.v3.Percent budget_percent = 1;

      // [...] This parameter is optional. Defaults to 3.
      google.protobuf.UInt32Value min_retry_concurrency = 2;
    }
    /* ... */
    // The maximum number of connections that Envoy will make to the upstream
    // cluster. If not specified, the default is 1024.
    google.protobuf.UInt32Value max_connections = 2;

    // The maximum number of pending requests that Envoy will allow to the
    // upstream cluster. If not specified, the default is 1024.
    google.protobuf.UInt32Value max_pending_requests = 3;

    // The maximum number of parallel requests that Envoy will make to the
    // upstream cluster. If not specified, the default is 1024.
    google.protobuf.UInt32Value max_requests = 4;

    // The maximum number of parallel retries that Envoy will allow to the
    // upstream cluster. If not specified, the default is 3.
    google.protobuf.UInt32Value max_retries = 5;
When a limit is hit, Envoy fails the request at once and increments a counter such as upstream_rq_pending_overflow or upstream_rq_retry_overflow. For HTTP requests the router also sets the x-envoy-overloaded header, per its circuit breaking docs.
Envoy puts the state-machine behaviour in a separate feature, outlier detection, which ejects (stops sending traffic to) individual hosts, never the whole cluster. Its defaults in the same release: eject a host after 5 consecutive 5xx, sweep every 10 s, eject for 30 s multiplied by the number of times it's been ejected, and never eject more than 10% of the cluster (outlier_detection.proto). Side by side:
| Resilience4j breaker | Envoy circuit breakers | Envoy outlier detection | |
|---|---|---|---|
| Unit | One dependency | One upstream cluster | One host in a cluster |
| Trips on | Failure or slow-call rate | Concurrency above a cap | Consecutive errors, or success-rate outliers |
| While tripped | All calls fail fast | Only calls over the cap fail | That host gets no traffic |
| Recovers | Half-open probes | As soon as load drops | After the ejection time |
6.3What to do when the breaker is open
A breaker that opens and returns an error has only made the failure faster. What the caller does instead is the real design question, and for the Pay click the answer depends on which dependency tripped:
| Fallback | Good for | Watch out for |
|---|---|---|
| Serve stale data from a cache | Profiles, catalogues, config | How stale is acceptable, and does anyone know it's stale |
| Degrade the feature | Recommendations, ratings, non-essential widgets | Hiding a failure nobody notices for weeks |
| Fail open: let the request through as if the check had passed | Rate limiters, feature-flag lookups | Security checks must never fail open |
| Queue for later | Writes that can be delayed: emails, analytics | The queue needs its own limits |
| Return an error | Payments, anything that must be correct | This is the honest default for critical paths |
Everything so far protects a caller from something it depends on. There's a second direction. The Pay click itself arrives at a server, and sometimes more clicks arrive than the server can handle.
07Overload and load shedding
Timeouts, retries and breakers protect a client from a bad dependency. Load shedding protects a server from its clients: when more work arrives than the server can do, something has to be refused. The only choice is whether you refuse it deliberately and cheaply, or accidentally and expensively.
7.1Why a busy server can serve nobody
Say the backend can handle 100 requests a second and a burst of clicks arrives at 150 a second. The extra work waits in a queue, and the server takes requests from it. In a FIFO queue (first in, first out) the server always takes the oldest. The problem is that clients don't wait forever. A client that gave up after a second has gone, but the server doesn't know that, and the request is still in the queue. Here's a small queue after a burst:
Because the server was busy the whole time, its processor sat at 100% and yet it served nobody. That's why we need two measures. Throughput is the number of requests the server completes per second, whether or not anyone is still waiting for the answer. Goodput is the number it completes within the client's deadline, which is the number that matters.
We can measure the effect with a simulation. One server handles 100 requests a second (each takes a random time averaging 10 ms). Normal load is 80 a second. From t=60 s to t=90 s a burst pushes it to 150 a second, then it returns to 80. Clients give up after 1 second. We try four ways of running the queue and, for each, clients that never retry or that retry up to 3 times when they time out:
fifois the plain queue from the scene above.deadlineis FIFO plus the deadline check: a request already past its deadline is dropped when it's dequeued.boundedalso rejects a request on arrival when 50 requests are already queued.lifoserves the newest request first whenever the queue has been busy for 100 ms (section 7.3 explains why).
def start(t):                       # called whenever the server is free
    while q:
        if policy == "lifo" and t - last_empty > 0.1:
            req = q.pop()           # queue busy for 100 ms: newest first
        else:
            req = q.popleft()
        if policy != "fifo" and t > req.deadline:
            continue                # expired: drop it without doing the work
        serve(req, t)               # takes expovariate(1 / 0.010) seconds
        return
# "bounded" also rejects on arrival when 50 requests are already queued.
# Retrying clients resend immediately when their 1 s timeout fires, up to 3 times.goodput, requests/s 0-30 30-60 60-90 90-120 120-150 150-180 ... 270-300
burst
fifo no retries 80 81 11 0 0 76 ... 79
fifo 3 retries 80 81 11 0 0 0 ... 0
deadline no retries 80 81 73 82 79 78 ... 79
deadline 3 retries 80 81 31 48 79 82 ... 79
bounded 3 retries 80 81 101 80 79 79 ... 80
lifo 3 retries 80 81 101 84 79 78 ... 79
fifo, 3 retries: offered 535/s during the burst, then ~320/s for the rest of
the run; ~100/s of completed work wasted every window after t=60Each row is a policy, each column is a 30-second window, and each number is goodput in requests per second. Before the burst every policy delivers about 80, all the offered load. Read the rows one by one:
- Plain FIFO keeps the server 100% busy through the burst and serves almost nobody for over a minute. The burst leaves about 1,500 requests queued (50 a second over capacity, for 30 seconds), and they drain at only 20 a second of spare capacity: 75 seconds.
- FIFO with retries never recovers. Every timed-out request comes back as a retry, so offered load, the rate at which requests arrive including retries, settles around 320 a second against a capacity of 100, long after the burst has gone. Goodput is zero for the remaining 210 seconds.
- One deadline check before starting each request fixes most of it. The server stops working on requests nobody is waiting for.
- A bounded queue or adaptive LIFO keeps goodput at the server's full capacity during the burst. Rejecting early is cheaper than timing out late.
Look again at the second row, because it's the alarming one: the burst ended after 30 seconds, and the outage lasted for the rest of the run. That behaviour has a name.
7.2Metastable failure
A burst that ends should leave a system that recovers. The FIFO-with-retries row didn't. Bronson, Aghayev, Charapko and Zhu's Metastable Failures in Distributed Systems (HotOS 2021) calls this a metastable failure: "a trigger causes the system to enter a bad state that persists even when the trigger is removed," held there by "a sustaining effect—often involving work amplification". Leaving it "requires a strong corrective push, such as rebooting the system or dramatically reducing the load." In our simulation the trigger was the 30-second burst, and the sustaining effect was the retries.
Perhaps the best-known real case is the AWS us-east-1 outage of 7 December 2021, which had this shape. Per AWS's summary, an automated scaling activity "triggered an unexpected behavior from a large number of clients," the surge overwhelmed networking devices between two internal networks, and the delays caused "even more connection attempts and retries," leading to "persistent congestion." The clients did have well-tested back-off behaviour, but "a latent issue prevented these clients from adequately backing off during this event." Recovery took about seven hours.
Now we know what to prevent. The remaining question is where in the path of a click to refuse the extra work, since the later it's refused, the more it has already cost.
7.3Shed early, shed cheaply
A request is cheapest to refuse at the first point it can be refused. Here are the places, from the client inwards:
The first and fourth steps need a closer look. Client-side throttling comes from Google's Handling Overload. Each client keeps two counts over the last couple of minutes, requests (attempted) and accepts (accepted by the backend), and rejects a new request locally with probability
max(0, (requests − K × accepts) / (requests + 1))K is a multiplier the operator picks, and Google says it "generally prefer[s] the 2x multiplier". When the backend accepts everything, requests is close to accepts, the top of the fraction is negative, and the probability is zero. When the backend starts rejecting, accepts falls behind and the probability rises, so clients cut their own traffic and the backend spends less of its capacity saying no.
The two queue rules from the fourth step come from Ben Maurer's Fail at Scale (ACM Queue, 2015), on how Facebook runs its services. Its CoDel variant (short for "controlled delay") says: if the queue hasn't been empty in the last N milliseconds, limit time in queue to M milliseconds. Facebook found M = 5 ms and N = 100 ms "tends to work well across a wide set of use cases." Adaptive LIFO serves FIFO normally and switches to newest-first (LIFO, last in first out) once a queue forms, because the oldest request's user has probably given up. In the simulation, the lifo policy uses the same 100 ms rule.
?Why LIFO? Isn't it unfair?
It's unfair to the requests at the back of a queue that's already too long, but they were probably going to time out anyway. Under FIFO everyone waits and most fail. Under LIFO the newest requests, whose clients are still waiting, succeed. Fairness in a queue that's overflowing means spreading failure evenly, and nobody benefits from that.
7.4Not all traffic is equal
Shedding blindly drops the checkout request as readily as the prefetch. Google's services tag every request with a criticality, one of CRITICAL_PLUS, CRITICAL, SHEDDABLE_PLUS and SHEDDABLE (Handling Overload), and shed from the bottom up. Even two classes help:
| Class | Examples | Under overload |
|---|---|---|
| User-facing, critical | Login, checkout, the page itself | Shed last |
| User-facing, optional | Recommendations, counts, previews | Shed early; degrade the UI |
| Batch and background | Reindexing, reports, prefetch | Shed first; retry later |
| Retries | Any retried request | Shed before first attempts of the same class |
Priority has to travel with the request the same way the deadline does. A background job that calls an API that calls a database should arrive at the database marked as background, or the database can't tell it from a user waiting on a page.
With the click's defences in place, from timeouts to shedding, what's left is to apply them to a real service in a sensible order.
08Applying it to your service
8.1A checklist, in order
Each step follows from a section above, in the order the chapter built them:
- Write down the SLI and SLO for your most important user journey, counted at the load balancer. Check it against the product of your critical dependencies (section 2.3).
- Add the two paging burn-rate alerts (14.4× over 1 h and 5 m; 6× over 6 h and 30 m) and delete the fixed-threshold error alert (section 3.3).
- Put a timeout on every outbound call, based on the dependency's p99.9, and propagate a deadline where your framework supports it (section 4).
- Retry at one layer, with full or decorrelated jitter, a cap, and a budget. Make every retried write idempotent (section 5).
- Bound every queue, and check the deadline when you dequeue (section 7).
- Size proxy concurrency limits from arrival rate × latency, not defaults (section 6.2).
- Run the recovery test from section 7.2: overload for a minute, drop back, and confirm the service recovers without help.
8.2What you trade for what
| You get | You pay | When the bill arrives |
|---|---|---|
| A target the whole team can read off a counter | A tighter SLO means a different engineering organisation for each nine | When the budget runs out and releases slow down |
| Timeouts that free threads | Some calls fail that would have succeeded slowly | When a timeout is set too tight and healthy calls trip it |
| Retries that hide brief failures | Extra load on the dependency, multiplied by every retrying layer | In an overload, as 64× the traffic |
| A breaker that lets a dependency recover | A fallback you have to design and keep honest | When a degraded feature goes unnoticed for weeks |
| Load shedding that protects the server | Some users get errors on purpose | When the shed class turns out to be one that mattered |
8.3Symptom, cause, fix
| Symptom | Likely cause | Fix |
|---|---|---|
| Stays down after the trigger is gone; CPU pinned, goodput near zero | Metastable: retries or queued expired work sustain the overload | Shed load or drain the queue; then add retry budgets and deadline checks |
| One slow dependency exhausts all threads | Missing or overlong timeout | Timeout from p99.9, bulkhead the pool per dependency |
| Database load spikes to many times normal during an incident | Retries at several layers | Retry at one layer, add a retry budget |
| Clients all retry in waves | Backoff without jitter | Full or decorrelated jitter |
503s with x-envoy-overloaded on a normal day | Envoy circuit-breaker defaults too low | Size max_requests and max_pending_requests from Little's Law |
| Duplicate charges or orders after timeouts | Non-idempotent write retried | Idempotency keys |
| Pages at night for blips; slow leaks never page | Fixed-threshold error alerts | Multiwindow burn-rate alerts |
| Breaker flaps open and closed | Window too small, or half-open lets in too much traffic | Larger window and minimum calls; fewer half-open probes |
09Summary
- Dependencies multiply. A click that needs five 99.9% services works about 99.5% of the time, and ten dependencies leave it near 99%. Critical dependencies need an extra nine, or a fallback.
- Each nine is ten times harder. 99.99% leaves 4.3 minutes a month, which has to be handled by automation, not people.
- An SLO is a count of good events over a window. Measure it where users feel it, and set the SLA looser than the SLO.
- The error budget is meant to be spent. It decides when to ship and when to fix, without an argument.
- Alert on burn rate over two windows. 14.4× over an hour spends 2% of a month's budget and deserves a page; a fixed error threshold doesn't.
- Every call needs a timeout, and call trees need a deadline. A call with none turns a dependency's latency into your threads. Check the deadline before doing work, not only while waiting.
- Retries multiply across layers. Four attempts at three layers is 64 attempts at the bottom. Retry at one layer, within a budget, and only operations that are idempotent.
- Backoff without jitter postpones the spike. In the simulation it took the last client 90 seconds; full jitter took 0.3.
- Circuit breakers fail fast so the dependency can recover. Envoy's "circuit breakers" are concurrency caps; its outlier detection is the state machine.
- Overload is survived by refusing work early. A bounded queue, a deadline check or adaptive LIFO kept goodput at capacity where plain FIFO with retries stayed at zero.
- A failure can outlive its trigger. Retries that sustain an overload make it metastable, so test recovery and not only normal load.
10Build this
A metastability test harness.
- Write a small HTTP service with a fixed capacity (a worker pool of 4 and a handler that sleeps 10 ms) and a load generator that sends at a fixed rate, times out at 1 second and optionally retries.
- Reproduce section 7.1: normal load at 80% of capacity, a 30-second burst at 150%, then back to 80%. Plot goodput per second. Confirm that FIFO plus retries never recovers.
- Add the fixes one at a time: a deadline check at dequeue, a bounded queue, adaptive LIFO, a client retry budget. Measure how long each takes to recover.
- Put Envoy in front with default circuit breakers, then with limits sized from Little's Law, and compare the overflow counters.
11Interview questions
beginnerWhat's the difference between an SLI, an SLO and an SLA?›
The SLI is the measurement: good events over valid events, such as the share of requests that succeed in under 300 ms. The SLO is the internal target for it over a window, such as 99.9% over 30 days. The SLA is an external contract, usually looser than the SLO, with penalties if it's missed.
beginnerWhy add jitter to exponential backoff?›
Because clients that fail together retry together. Without jitter, a thousand clients that failed at the same moment all retry at 1 s, then 2 s, then 4 s, and each wave hits the same limit. Jitter spreads them out. In a simulation of 1,000 clients against a server taking 10 per millisecond, unjittered backoff took 90 seconds to serve everyone; full jitter took 0.3 seconds with a seventh of the calls.
intermediateWhat is a burn rate, and why alert on it?›
The ratio of your current error rate to the rate that would use up the error budget exactly at the end of the SLO window. For a 99.9% SLO, a 1.44% error rate is a burn rate of 14.4, which spends 2% of a 30-day budget in an hour. Alerting on burn rate ties the page to the thing you care about, how fast you're using up reliability, instead of to an arbitrary error threshold.
intermediateA request goes through browser, frontend, backend and database, and each of the first three retries 3 times. What's the worst case at the database?›
Each layer makes up to 4 attempts, and the attempts multiply: 4 × 4 × 4 = 64 attempts for one user action. That's the SRE book's own example. The fix is to retry at only one layer and cap retries with a budget, so a failing database sees close to its normal load instead of 64 times it.
intermediateWhat does a circuit breaker do in each of its states?›
Closed: calls pass, and outcomes are recorded in a sliding window. When the failure rate crosses a threshold (50% by Resilience4j's default, after at least 100 calls), it opens. Open: calls fail immediately without reaching the dependency, for a wait period (60 s by default). Half-open: a small number of trial calls (10) are allowed; if they succeed it closes, otherwise it reopens.
deepWhat's a metastable failure, and how do you prevent one?›
A failure where a temporary trigger pushes the system into a bad state that persists after the trigger is gone, because of a sustaining effect such as retries or work on already-expired requests. Load that the system handled before the trigger is now more than it can handle. Prevention is removing the sustaining effect in advance: retry budgets, jitter, deadline checks at dequeue, bounded queues and load shedding. And test recovery by overloading and then returning to normal load.
deepWhy would a server process its queue LIFO under load?›
Once a queue has formed, the oldest requests have waited longest, and their clients have probably timed out. Serving them first spends capacity on work nobody will read, so everyone fails. Serving newest first gives recent requests, whose clients are still waiting, a good chance of success. Facebook uses adaptive LIFO (FIFO normally, LIFO when a queue forms) together with a CoDel-style bound on queueing time.
deepEnvoy returns 503s with x-envoy-overloaded on a normal day. What's happening?›
A cluster circuit breaker is overflowing, most likely max_requests or max_pending_requests, both 1,024 by default. By Little's Law a service at 20,000 requests a second and 60 ms latency has about 1,200 requests in flight, so the default is too small. Check the upstream_rq_pending_overflow and upstream_rq_active_overflow counters, then size the limits from arrival rate × latency with headroom.
12Go deeper
Your SLO is 99.95% per 30 days. How much full outage can you afford?›
21.6 minutes: 0.05% of 43,200 minutes.
A client library retries with min(cap, base × 2^n) and no randomness. What goes wrong?›
Clients that failed together stay synchronised and retry in waves, each wave meeting the same capacity limit. Add full or decorrelated jitter.
gRPC retry throttling: when does a client stop retrying?›
When its token count falls to half of maxTokens or below. Each failure costs one token and each success earns tokenRatio.
Why check the deadline when dequeuing a request, not only when it arrives?›
Because it may have expired while it waited. Processing it spends capacity on a response nobody will read, which is how an overload sustains itself.
Distributed systems from the ground up: unreliable networks, acknowledgements, timeout and retry, and why NFS makes its operations idempotent. Free online
Walks through six alerting schemes, from a plain error threshold to multiwindow multi-burn-rate, with the trade-offs of each. sre.google
Client-side throttling, criticality, retry budgets, deadline propagation and the 64× retry example. Handling Overload, Cascading Failures.
The vocabulary for failures that outlive their trigger: vulnerable state, trigger, sustaining effect. PDF
The simulation that made full jitter the default recommendation. AWS Architecture Blog
How Facebook runs services under overload: controlled delay, adaptive LIFO and concurrency control. CACM
The rule of the extra nine and how to reason about critical dependencies. CACM
Every limit and default in section 6.2, documented in the API definitions. v1.31.0
Retry policy, hedging policy and retry throttling, as specified. proposal
13Related chapters
The queueing arithmetic under every section here: the utilisation curve, Little's Law, hedged requests and coordinated omission. Chapter 16.
How the SLIs in this chapter get measured: counters, histograms, the Prometheus data model and traces. Chapter 39.
Where SLOs and capacity numbers enter a design, before the boxes are drawn. Chapter 38.
The accept queue and SYN retries: load shedding the kernel does for you, silently. Chapter 10.